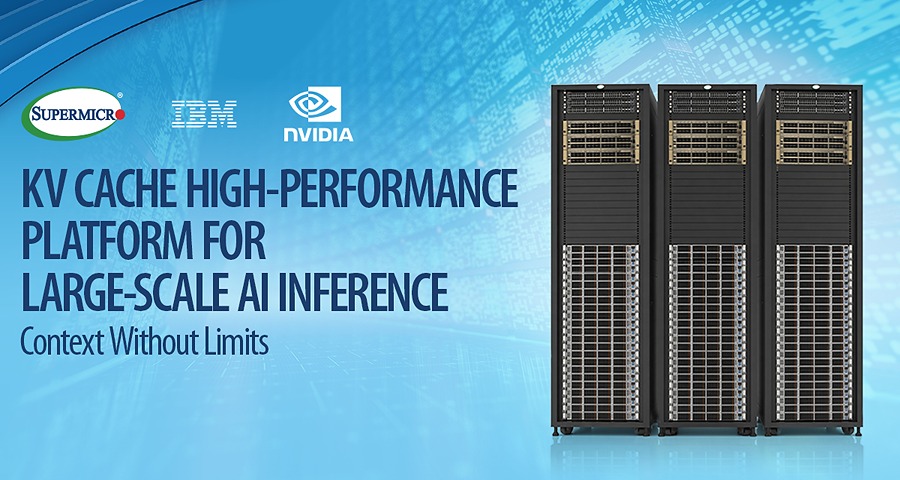
SAN JOSE, CA, Nov 9, 2026 – Supermicro has announced a new key-value (KV) cache storage solution developed with IBM and NVIDIA to reduce redundant computation during AI inference. The architecture combines Supermicro Petascale all-flash storage servers using AMD EPYC 9005 series (“Turin”) processors, IBM storage scale software, NVIDIA Dynamo and NVIDIA Spectrum-X ethernet networking.
“As AI workloads expand from training to inference, enterprises and neoclouds deploying high-throughput inference workloads characteristic of agentic AI and long-context, multi-turn generative AI need to remove bottlenecks to improve GPU efficiency,” said Charles Liang, president and CEO of Supermicro. “Our solution with IBM and NVIDIA clearly demonstrates these performance benefits.”
Persistent KV Cache for AI Inference
During AI inference, LLMs generate key-value states that can be reused across subsequent requests. The solution stores these states in shared network storage, allowing GPU nodes and clusters to access previously processed context without repeating computations. According to Supermicro, this approach can improve GPU utilization and inference throughput while supporting availability and nondisruptive cache expansion.
Performance Testing and Deployment
In joint testing by Supermicro and NVIDIA using a 120-billion-parameter LLM, persistent KV caching delivered up to 56 times faster time to first token (TTFT) with 130,000-token prompts. As input length increased from 30,000 to 130,000 tokens, TTFT increased by 0.377 seconds with persistent KV caching, compared with 29.55 seconds without it.
“Enterprises need a fundamentally better way to scale AI inference. Together, IBM, Supermicro, and NVIDIA are delivering a high-performance, resilient KV cache solution that helps customers maximize their GPU investments, scale independently of compute, and significantly improve infrastructure efficiency,” said Sam Werner, GM, IBM Storage. “This collaboration represents an important step toward making enterprise AI inference more scalable, reliable, and cost-effective.”
“Agentic AI and long-context applications depend on reusing context efficiently across many steps, and NVIDIA Dynamo helps orchestrate distributed inference so enterprises can get more usable throughput from every GPU,” said Shruti Koparkar, NVIDIA AI Inference product lead. “By pairing NVIDIA Dynamo and Spectrum-X Ethernet with Supermicro Petascale storage servers and IBM Storage Scale, this KV cache solution creates a high-performance shared storage tier that can reduce redundant computation, improve time-to-first-token and help customers scale resilient AI inference services.”
Source: Super Micro
About Super Micro Computer
Super Micro Computer is a U.S. technology company founded in 1993 and headquartered in San Jose, CA. It designs and manufactures server and storage systems, networking devices and server management software. The company also develops components such as motherboards, power systems and chassis used in its hardware platforms. Supermicro provides products for enterprise data centers, cloud computing, AI, telecommunications and edge computing environments. Its portfolio includes servers, AI systems, storage platforms, IoT systems, switches and related support services. The company designs and manufactures products in facilities in the United States, Taiwan and the Netherlands. Its systems support a range of processors, memory configurations, GPUs, storage and networking options, along with air and liquid cooling methods. Supermicro serves global customers across enterprise and service provider markets. The company employs about 5,000 people worldwide.
